Running a 0.5B LLM on Seven ESP32-S3 Boards
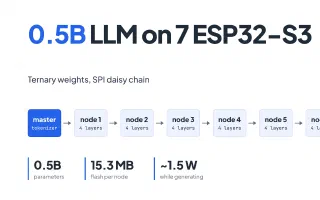
How an open-source cluster of seven ESP32-S3 microcontrollers splits a Qwen2-0.5B model into 1.58-bit ternary layers, why it fits in 16 MB of flash per board, and why it is slow.
Blog posts tagged “Edge AI”
How an open-source cluster of seven ESP32-S3 microcontrollers splits a Qwen2-0.5B model into 1.58-bit ternary layers, why it fits in 16 MB of flash per board, and why it is slow.
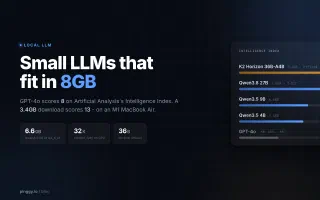
Which open-weight LLMs actually fit in 8GB of VRAM or RAM in 2026, with measured file sizes, KV cache math from published configs, and Ollama commands for Qwen3.5, Gemma 4, Ministral 3, Granite 4.1, Nemotron 3 Nano, and Phi-4-mini.
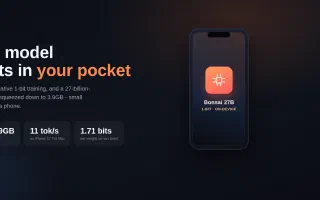
Bonsai 27B compresses a 27B-parameter Qwen3.6 model to 3.9GB using native 1-bit weights and runs on an iPhone at 11 tok/s. Here's what it gives up.
Learn what TurboQuant is, the math behind Google's new compression method, and how Gemma 4 combines efficient architectures and edge runtimes to run on phones and other edge devices.