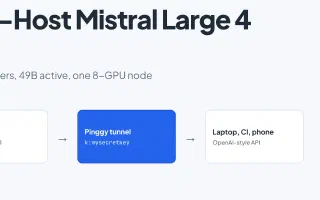
How to Self-Host Mistral Large 4 and Reach It From Anywhere
Mistral Large 4 ships open weights: 1T parameters, 49B active, 1M context. Here is what it takes to serve it with vLLM on one 8-GPU node and expose the API safely with a Pinggy tunnel.
Blog posts tagged “AI Models”
Mistral Large 4 ships open weights: 1T parameters, 49B active, 1M context. Here is what it takes to serve it with vLLM on one 8-GPU node and expose the API safely with a Pinggy tunnel.
My pick for best overall AI image-to-video generator is FLUX 3 Max on fal: #1-tier 1,139 Elo, ~22x faster than Seedance 2.5. Plus picks for speed and budget.
Jev, Liquid d1-ultra, pplx-decider, Microsoft-Decision-1, OpenAI Decisions, Cloudflare Clef and Strands Decider 2B compared on price, inputs and three independent leaderboards, with one run locally on an M3 Pro.
The best open-weight speech-to-text models you can self-host in October 2026, ranked on the Hugging Face Open ASR Leaderboard: Qwen3-ASR, Cohere Transcribe, Granite Speech, Parakeet, Voxtral, Whisper and more, with licenses, speed and serving.
TypeSafe's Jev is closed, hosted and waitlisted, so the open reimplementations started landing within a day. Laya, Kev, SemIf, NanoJev and jevlike, ranked by GitHub stars, with latency measured on an M3 Pro, the independent benchmark where Jev still wins on accuracy, and what each one actually needs to run.
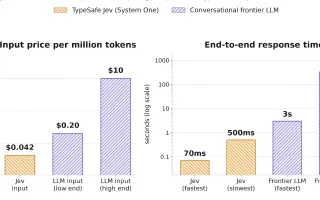
TypeSafe's Jev is a System One model that returns typed decisions instead of text: 70-500ms latency, $0.042 per million input tokens with output free, and 0% structured-output errors. Here are the three jobs it actually fits, the honest benchmark picture against GPT-6 Astra and Claude, and the tasks where it is the wrong tool.
A practical checklist for reviewing an all-in-one AI tools subscription before you buy: what's actually included, testing it against real work, output quality, usage limits, team access, and privacy controls.
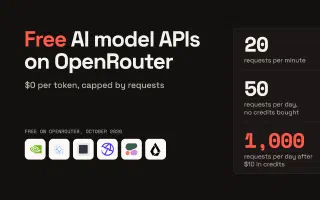
How to get free AI model APIs on OpenRouter in late 2026: the real limits (20 requests a minute, 50 or 1,000 a day), the current free catalog (Inkling, Nemotron 3 Ultra, Nemotron 3.5 Super VL, Gemma 4), what free endpoints log, and working code.
Understand Mixture of Experts (MoE) architecture in LLM models - how it works, why it's efficient, and which models use it. Learn about sparse activation, routing, and performance benefits.
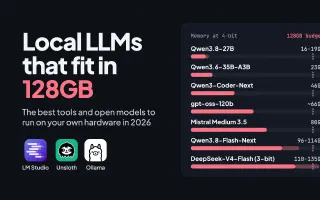
The best local LLM tools in 2026 (LM Studio, Unsloth, Ollama, LocalAI and more) and the open-weight models that fit in 128GB of memory, with measured 4-bit sizes for Qwen3.8, Gemma 4 and gpt-oss.