In this article

Most developers hit the same wall once they start building with large language models: the prototype works, and then the API bill starts tracking every experiment. Frontier models still bill by the token. Claude Opus 5.5 lists at $4 per million input tokens and $20 per million output tokens, and that adds up fast once you’re calling it in a loop.
Search “free AI API unlimited tokens” and you’ll find a pile of posts promising a way around that. The honest version is less exciting but more useful: OpenRouter gives you no-credit-card access to a rotating set of models at $0 per token, but “unlimited” isn’t the right word. You get 20 requests per minute and either 50 or 1,000 requests per day, depending on whether you’ve bought $10 of credits. No token cap, but a very real request cap.
The free list also turns over fast. In July 2026, Owl Alpha, Tencent Hy3, Qwen3 Coder and gpt-oss-120b were all free on OpenRouter; none of them is free today, and the lineup is led by Thinking Machines’ 975-billion-parameter Inkling and NVIDIA’s Nemotron family. Every limit, price and model ID below was checked against OpenRouter’s live API and model pages on October 27, 2026.
Here’s the current free lineup at a glance before we get into the mechanics:
| Model | Size | Context (free) | Best For |
|---|---|---|---|
| Thinking Machines Inkling | 975B / 41B active MoE | 1M tokens | Coding and agent harnesses, text, image and audio input |
| NVIDIA Nemotron 3 Ultra | 550B / 55B active MoE | 1M tokens | General reasoning, agent orchestration |
| NVIDIA Nemotron 3.5 Super VL | 120B / 12B active MoE | 1M tokens | Documents, screenshots and video input |
| Google Gemma 4 | 31B dense / 26B-A4B MoE | 262K tokens | Multimodal input, function calling, 140+ languages |
| Poolside Laguna S 2.1 | 118B / 8B active MoE | 262K tokens | Coding agents, going away October 31, 2026 |
| openrouter/free | Router over the free models | 200K tokens | Code that should keep working as models rotate |
That table covers the six worth knowing individually. Counting embedding, reranking, speech and “decision” models, OpenRouter lists 28 model IDs ending in :free right now, 16 of them chat models, and we get to the rest further down.
Summary
What “free” means on OpenRouter: Models whose IDs end in :free cost $0 per input and output token. The limit is on requests, not tokens: 20 requests/minute always, plus 50 requests/day until you’ve bought $10 of credits in total, and 1,000 requests/day after that. The tier follows all-time purchases, so spending your balance down doesn’t drop you back to 50.
Getting started: Create an account at openrouter.ai/keys (email or GitHub, no card needed), generate an API key, and call the OpenAI-compatible endpoint at https://openrouter.ai/api/v1/chat/completions with any model ID ending in :free. A GET to https://openrouter.ai/api/v1/key tells you how many free requests you have left today.
Free models worth knowing right now (October 2026, verify before you rely on one): Inkling, Nemotron 3 Ultra, Nemotron 3.5 Super VL, Gemma 4 and Laguna S 2.1 (until October 31), plus the openrouter/free router. Owl Alpha, Tencent Hy3, Qwen3 Coder and gpt-oss were free in July and aren’t anymore.
The catch beyond rate limits: free endpoints often log what you send. NVIDIA, Thinking Machines and Poolside all say on their OpenRouter model pages that free-tier traffic is logged or may be used to improve their models, so keep confidential data off them.
The reliability tip: free models rotate out with little warning. List 2-3 free fallbacks in OpenRouter’s models array instead of hardcoding a single model ID.
These free models work beyond raw API calls too. Coding agents like OpenCode ship OpenRouter as a built-in provider, and we’ve walked through running Hermes Agent on OpenRouter's free models end to end. This guide sticks to the free tier itself: what it costs, what it limits, and which models are on it right now.
The Free Tier: Rate Limits, Not Token Limits
This is the part most “unlimited tokens” articles get wrong. OpenRouter’s free models charge $0.00 per input token and $0.00 per output token, so there is genuinely no token-based billing. What every account does have is a request cap, documented on OpenRouter’s limits page:
- 20 requests per minute, always, regardless of account status
- 50 requests per day if you’ve bought less than $10 of credits in total
- 1,000 requests per day once your credit purchases reach $10
The docs say the daily tier “is selected by all-time credits purchased”, so it counts what you’ve bought over the account’s lifetime, not your current balance. Once you cross $10, the higher ceiling stays even if your balance later drops to zero. In practice the 1,000 tier starts at 9 credits, one below the threshold, which OpenRouter says absorbs rounding and top-up fees.
So a 100,000-token conversation costs you one request, same as a two-word prompt, and an agent loop that calls the model dozens of times per task hits the daily ceiling long before any token count matters. Two more things can stop you: Cloudflare’s DDoS protection blocks requests that “dramatically exceed reasonable usage”, and a negative credit balance can block free models too, with 402 errors. That mostly happens if you use paid models alongside free ones and let the balance run dry.
Checking How Many Free Requests You Have Left
OpenRouter reports the daily counter on its key endpoint:
curl https://openrouter.ai/api/v1/key \
  -H "Authorization: Bearer $OPENROUTER_API_KEY"
The response includes a free_model_daily_requests object with used, limit and remaining counts for the current UTC day. An agent can check it before a long run instead of discovering the ceiling through 429 “Rate limit exceeded” errors halfway through. It doesn’t report the per-minute limit, though. When you do hit a limit, the 429 response carries X-RateLimit-* headers describing the one you hit.
Getting Set Up
- Go to openrouter.ai/keys and sign up with email or GitHub. No credit card is needed for free models.
- Generate an API key on that page. You can optionally cap each key with a credit limit.
- (Optional, recommended) Buy credits. Pay-as-you-go carries a 5.5% platform fee on credit purchases (8% on the Business plan), and $10 of purchases in total is what raises your free-model ceiling to 1,000 requests a day. It’s a one-time threshold, not a subscription.
- Call the API. Free models carry a
:freesuffix on their model ID, and OpenRouter’s Free Models collection is the fastest way to see what’s available today.
If you only plan to use free models, you can stop at step 2 and spend $0. The $10 is purely about the daily ceiling, and it’s worth buying once a project becomes something you use every day, because 50 requests disappear fast when you’re iterating on prompts. Before you buy, note that OpenRouter’s FAQ says OpenRouter reserves the right to expire unused credits a year after purchase.
Calling a Free Model
Because OpenRouter mirrors the OpenAI API shape, you can use curl directly or the standard openai Python/JS SDK pointed at a different base URL. Here’s the raw HTTP version:
curl https://openrouter.ai/api/v1/chat/completions \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $OPENROUTER_API_KEY" \
  -d '{
    "model": "nvidia/nemotron-3-ultra-550b-a55b:free",
    "messages": [
      {"role": "user", "content": "Explain the difference between MoE and dense transformer architectures in two sentences."}
    ]
  }'
And the same call using the official OpenAI Python SDK, just repointed at OpenRouter:
from openai import OpenAI

client = OpenAI(
    base_url="https://openrouter.ai/api/v1",
    api_key="sk-or-v1-your-key-here",
)

response = client.chat.completions.create(
    model="nvidia/nemotron-3-ultra-550b-a55b:free",
    messages=[
        {"role": "user", "content": "Explain the difference between MoE and dense transformer architectures in two sentences."}
    ],
)

print(response.choices[0].message.content)
No OpenRouter-specific SDK, no custom client library. If your code already talks to the OpenAI API, changing base_url and the model string is the entire migration.
Handling Rotation and Rate Limits with Fallback Models
The single most important production tip for the free tier: don’t hardcode one free model. Free variants get pulled or repriced without much warning. Between July and late October 2026, qwen/qwen3-coder:free, openai/gpt-oss-120b:free, tencent/hy3:free and nvidia/nemotron-3-super-120b-a12b:free have all disappeared, and any code pinned to them now fails. OpenRouter’s models array lets you list several candidates in priority order in one request:
{
  "models": [
    "nvidia/nemotron-3-ultra-550b-a55b:free",
    "google/gemma-4-31b-it:free",
    "nvidia/nemotron-3.5-lightning:free"
  ],
  "messages": [
    {"role": "user", "content": "Summarize this changelog in three bullet points."}
  ]
}
By default any error can send the request to the next model, including context-length errors, moderation flags, rate limiting and provider downtime. You’re billed for whichever model answered, and its ID comes back in the response’s model field, so you can log which fallback fired. Keep every entry a :free model: if the list falls through to a paid one, you pay that model’s rate.
If you’d rather not manage a list at all, openrouter/free is a router that picks a free model at random from the ones that support what your request needs, such as tool calling, structured outputs or image input. It trades predictability for convenience: you don’t control which model answers, but your code keeps working as the free lineup changes.
How Free Models Leave OpenRouter
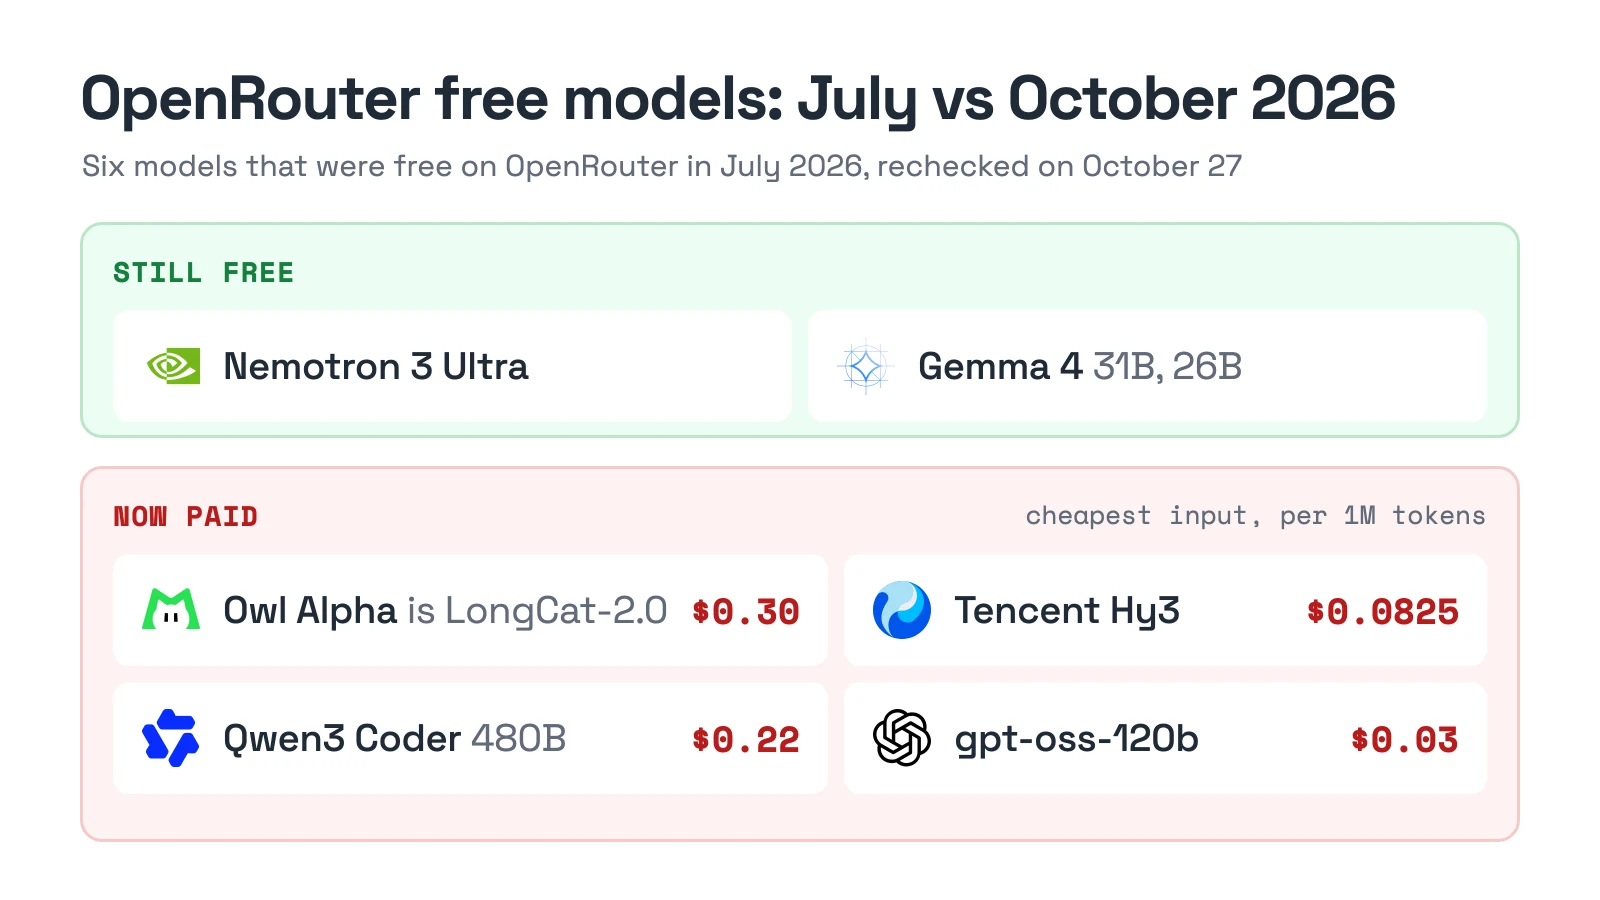
Prices: cheapest OpenRouter provider per million input tokens, October 27, 2026.
Three months ago the free list looked different. In July, Nemotron 3 Ultra, Gemma 4, Owl Alpha, Tencent Hy3, Qwen3 Coder and gpt-oss-120b were all free. Only the first two still are, and the other four show the different ways a free listing ends.
Owl Alpha turned out to be Meituan’s LongCat-2.0. It was a stealth model, a prerelease checkpoint OpenRouter serves for free under a codename while the lab collects real-world usage. At the end of June, Meituan’s LongCat team introduced LongCat-2.0 as “the full model behind Owl Alpha”: 1.6 trillion parameters, about 48B active per token, and a 1M-token context. The weights are on Hugging Face under the MIT license, and on OpenRouter meituan/longcat-2.0 costs $0.30/M input and $1.20/M output, currently shown as a discounted price.
The same thing happened again this fall. A stealth model called Space Bunny left OpenRouter on October 5 and came back on October 19 as MiniMax M3.1 Flash, free for 72 hours and now paid, from $0.143/M input. As of October 27 there’s no stealth model on the list, so don’t plan around one.
Tencent Hy3’s free window closed. Tencent had set July 21 as the end date for the free listing, and Hy3 is now paid only, from $0.0825/M input and $0.33/M output through Tencent’s own endpoint.
Qwen3 Coder and gpt-oss-120b lost their :free variants. Both are still on OpenRouter as paid models: Qwen3 Coder from $0.22/M input, and gpt-oss-120b from $0.03/M input and $0.15/M output across about two dozen providers. At that price gpt-oss is close to free anyway. Smaller free models from July went the same way: the free Llama 3.3 70B, Llama 3.2 3B and Hermes 3 405B variants are gone, and NVIDIA’s Nemotron 3 Super lost its free endpoint in late October (paid from $0.08/M input). DeepSeek still has no free model, though V4.1 Flash is listed at $0.14/M input and $0.42/M output.
The Free Model Catalog Right Now
OpenRouter’s free lineup is a moving target: models get added when labs promote a launch, and pulled when the promotion ends. On October 27, 2026, the API lists 28 model IDs ending in :free: 16 chat models, seven embedding and reranking models, two text-to-speech models and three “decision” models that return scored answers instead of free text. By last week’s usage, OpenRouter’s Free Models page ranks Nemotron 3 Ultra, Nemotron 3.5 Super VL and Nemotron 3.5 Lightning as the most used. Five of the chat models are worth calling out individually.
Thinking Machines Inkling (975B-A41B)
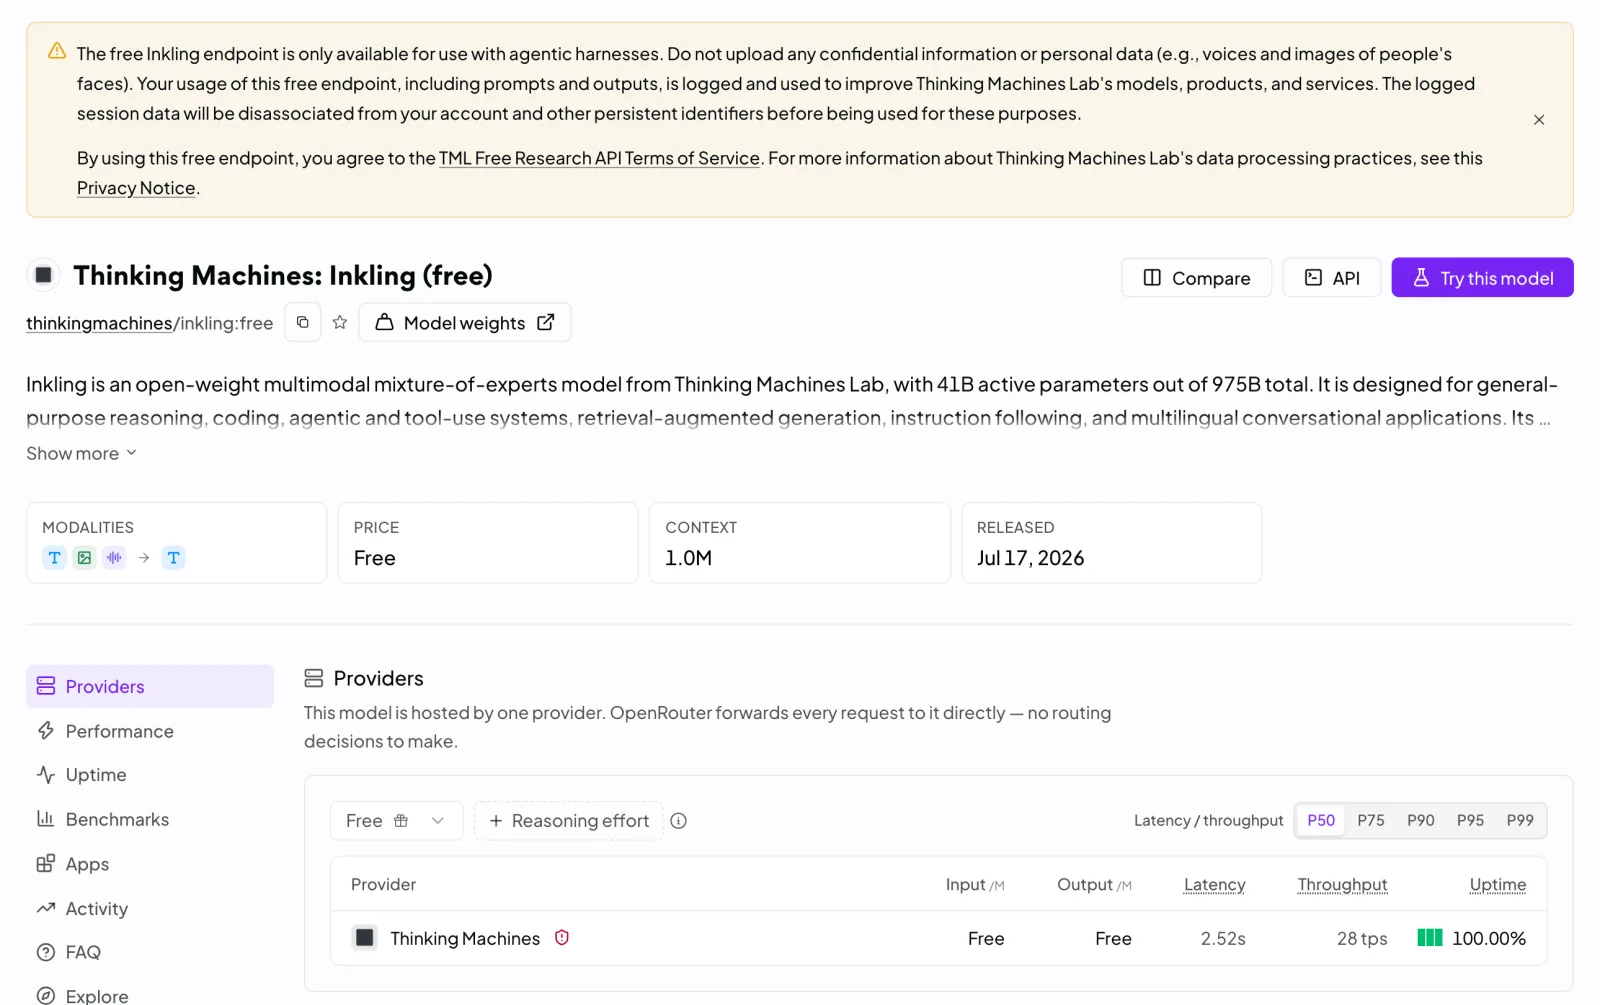
Screenshot: openrouter.ai/thinkingmachines/inkling:free, October 2026.
Inkling is the biggest model on the free list. Thinking Machines Lab released it on July 15, 2026, trained from scratch with the full weights available: a Mixture-of-Experts with 975B total parameters and 41B active, text, image and audio input, and up to 1M tokens of context. The weights are on Hugging Face under Apache 2.0. On OpenRouter the free endpoint serves the full 1M context, while the paid listing ($1.00/M input, $4.05/M output) tops out at 524K. The lab is frank about where it stands: “Inkling is not the strongest overall model available today, open or closed”, and pitches it as a base for customization.
Read the notice at the top of the model page before you wire it in. The free endpoint “is only available for use with agentic harnesses”, and Thinking Machines logs its prompts and outputs to improve its models, after separating them from your account. Use it for coding-agent experiments, not confidential work. Its smaller sibling, thinkingmachines/inkling-small:free (276B total, 12B active), is free as well.
NVIDIA Nemotron 3 Ultra (550B-A55B)
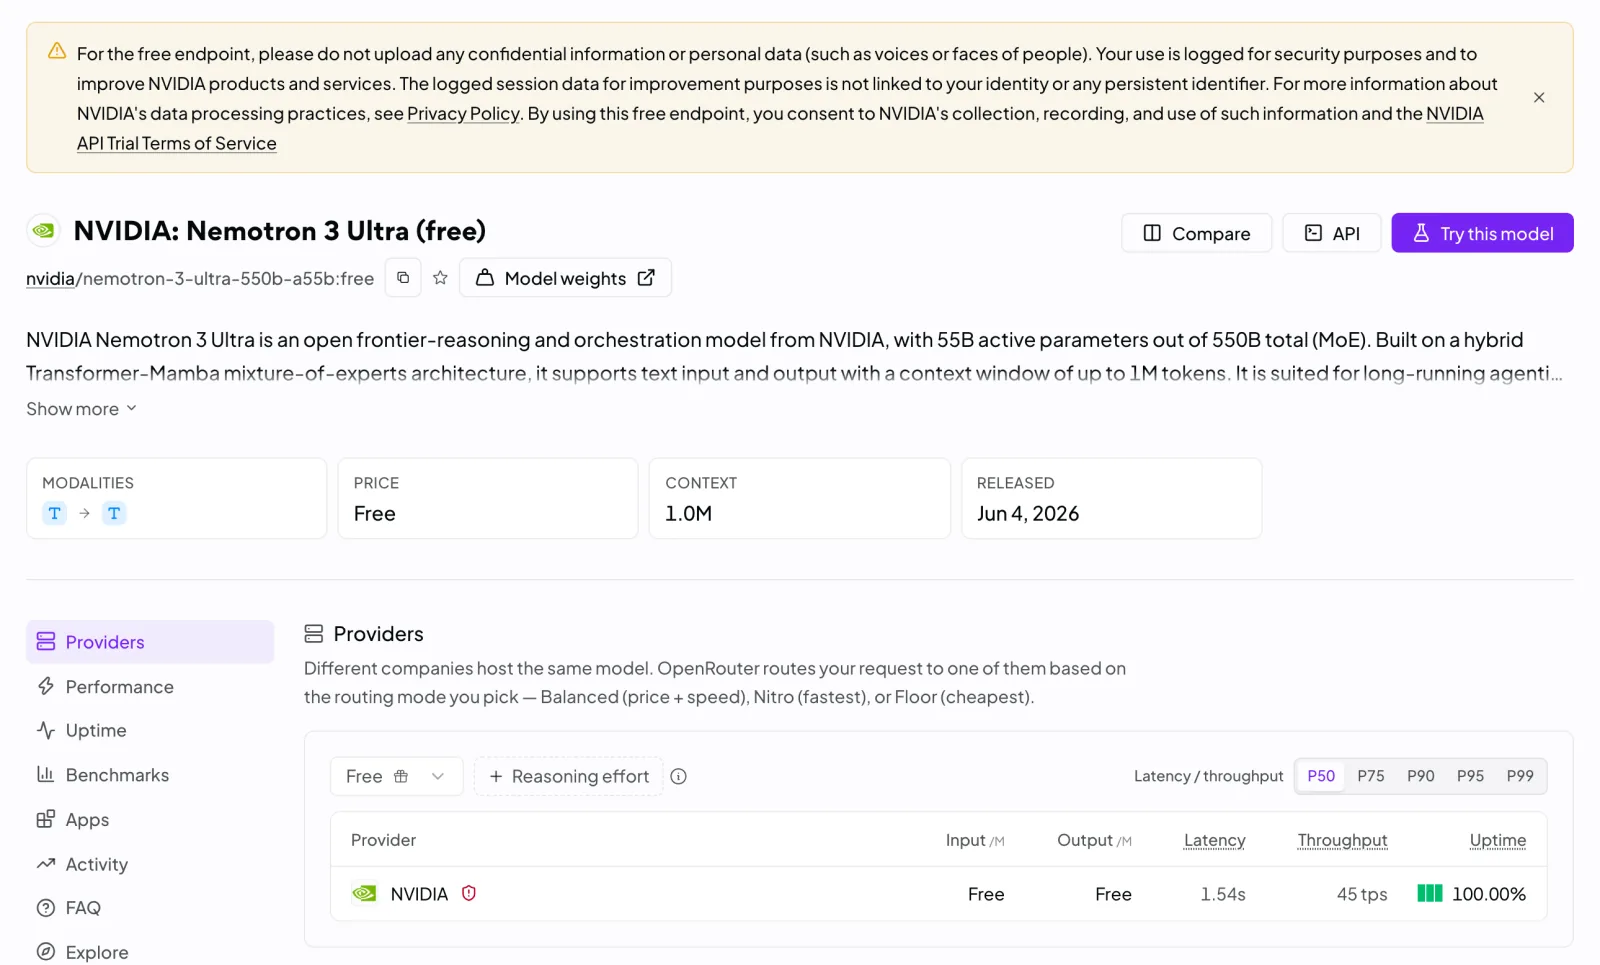
Screenshot: openrouter.ai/nvidia/nemotron-3-ultra-550b-a55b:free, October 2026.
NVIDIA Nemotron 3 Ultra, released June 4, 2026, is one of the two July picks that’s still free. It’s a 550B-parameter MoE with 55B active per token, built on a hybrid Transformer-Mamba architecture that NVIDIA designed for high-throughput agent pipelines. NVIDIA serves the free endpoint itself, with a 1M-token context and up to 65,536 output tokens. The paid endpoints, from $0.40/M input and $1.76/M output, stop at 262K context, so on this model the free tier is the bigger one. NVIDIA’s notice on the page says use of the free endpoint “is logged for security purposes and to improve NVIDIA products and services”.
NVIDIA Nemotron 3.5 Super VL (120B-A12B)
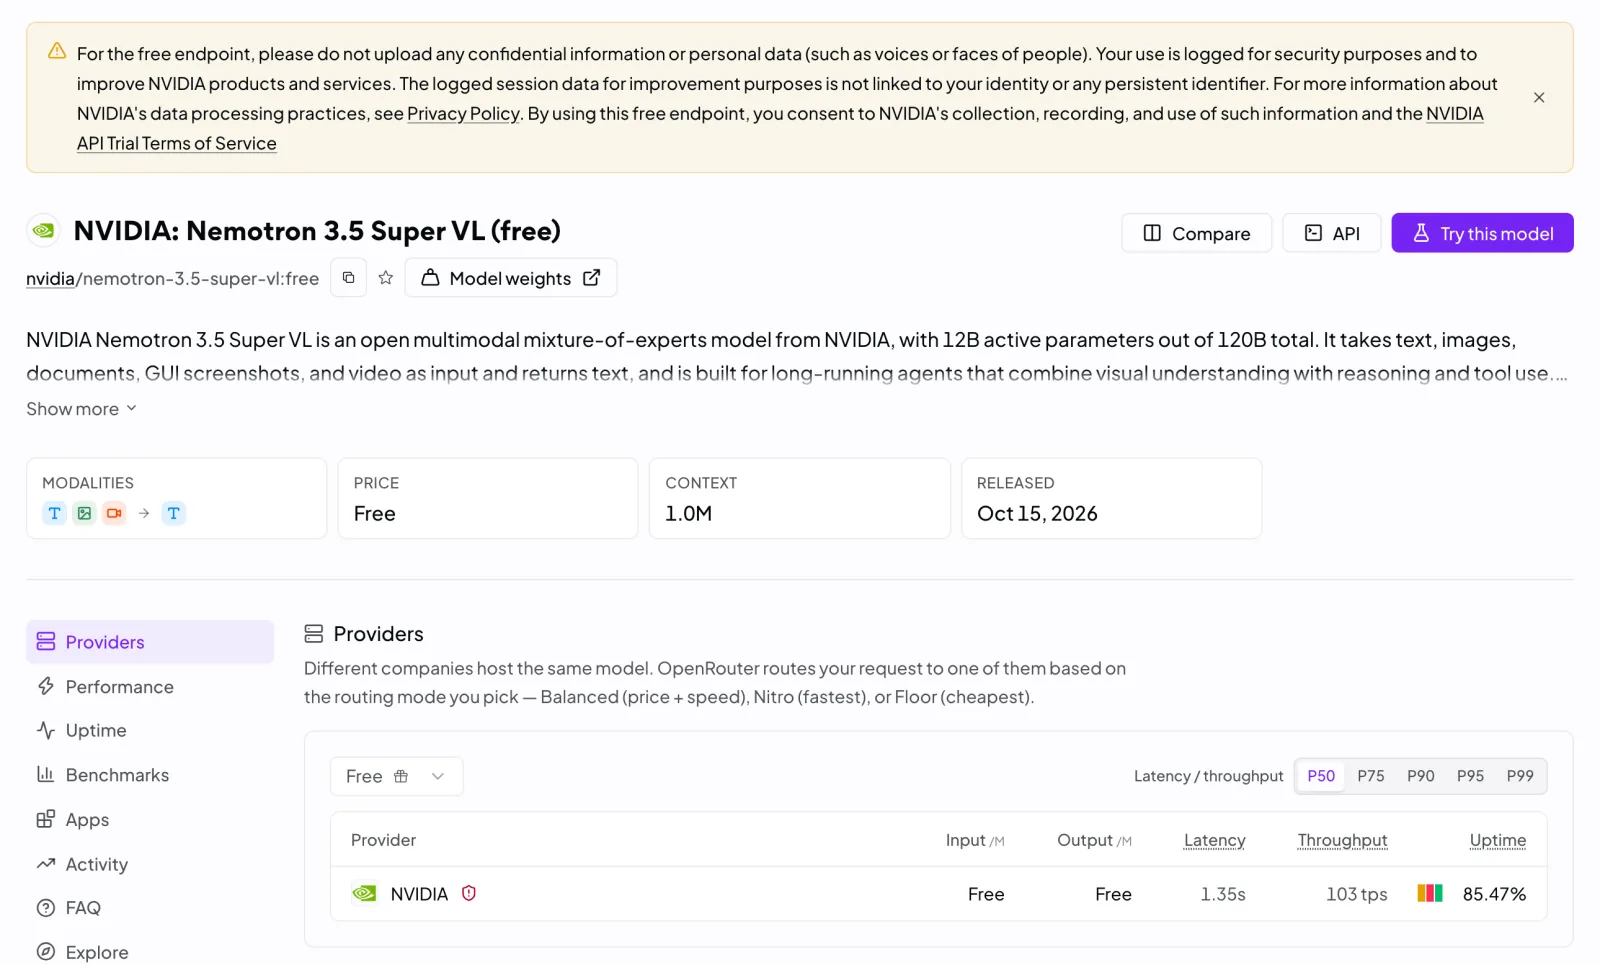
Screenshot: openrouter.ai/nvidia/nemotron-3.5-super-vl:free, October 2026.
Nemotron 3.5 Super VL is the newest model in this guide, released October 15, 2026. It’s a 120B-parameter MoE with 12B active that takes text, images, documents, GUI screenshots and video and returns text, with a 1M-token context and reasoning switched on by default (you can turn it off or give it a token budget). That makes it the free pick for document extraction, screenshot-driven agents and video understanding. The same NVIDIA logging notice sits on its page. Paid endpoints start at $0.06/M input. For speed over size, nvidia/nemotron-3.5-lightning:free (30B total, 3B active, text only, 1M context) is the high-throughput option in the same family.
Google Gemma 4 (31B and 26B-A4B)
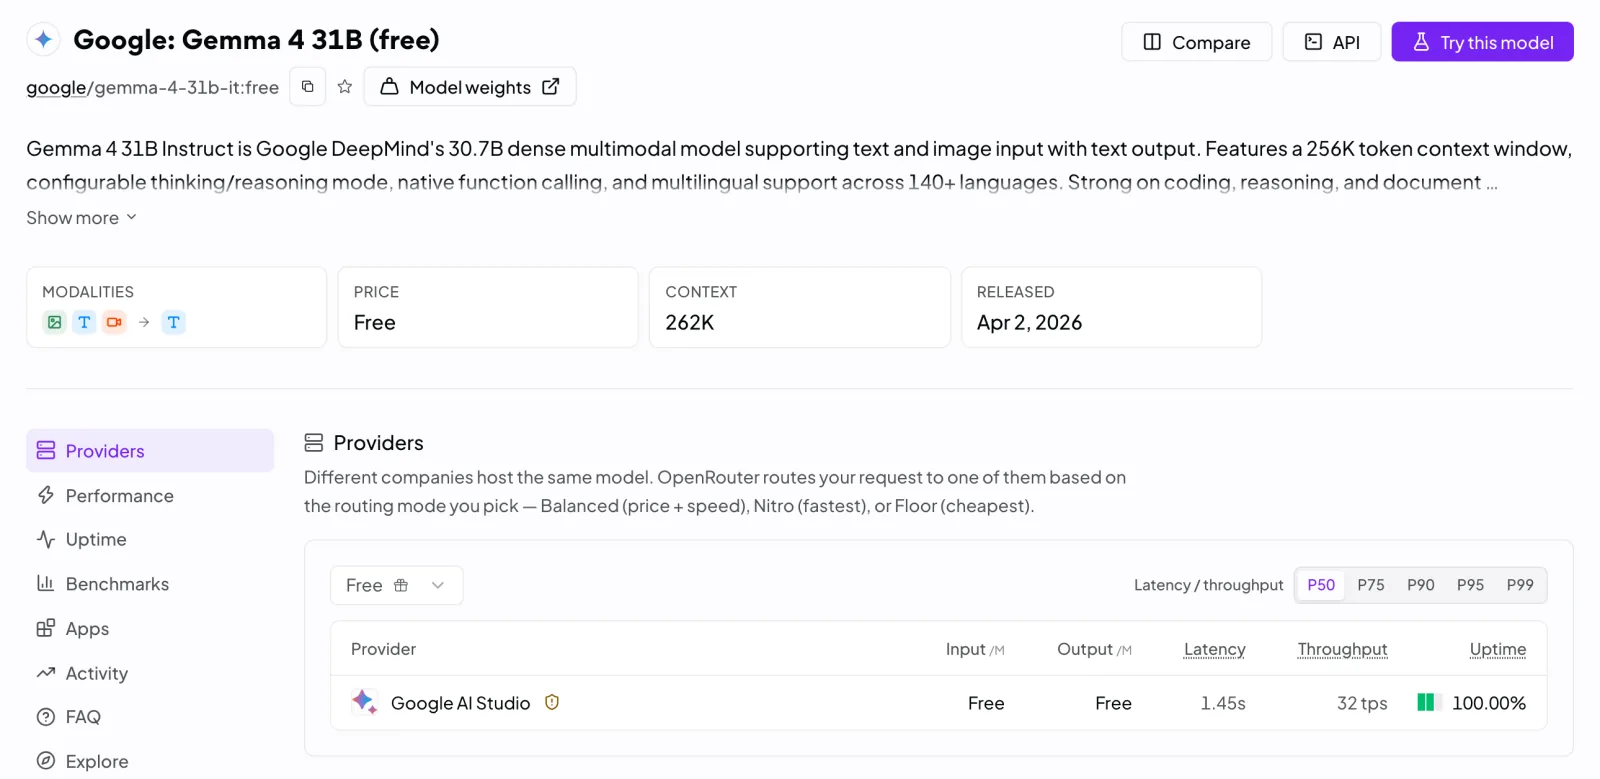
Screenshot: openrouter.ai/google/gemma-4-31b-it:free, October 2026.
Google DeepMind’s Gemma 4 family, released April 2, 2026, is the other July pick that’s still free, and both variants survived. google/gemma-4-31b-it:free is the 30.7B dense model: no MoE routing, so it’s the slower of the two, but it’s the one to reach for when you want the best single answer. `google/gemma-4-26b-a4b-it:free` is the MoE sibling, with 25.2B total and 3.8B active parameters, landing close to the 31B model’s quality while responding faster. Google AI Studio serves both for free with a 262K context, up to 32,768 output tokens, image and video input, configurable thinking, native function calling and 140+ languages, under the Apache 2.0 license. Unlike the NVIDIA and Thinking Machines pages, Gemma’s free page shows no logging notice.
Poolside Laguna S 2.1 - Going Away October 31
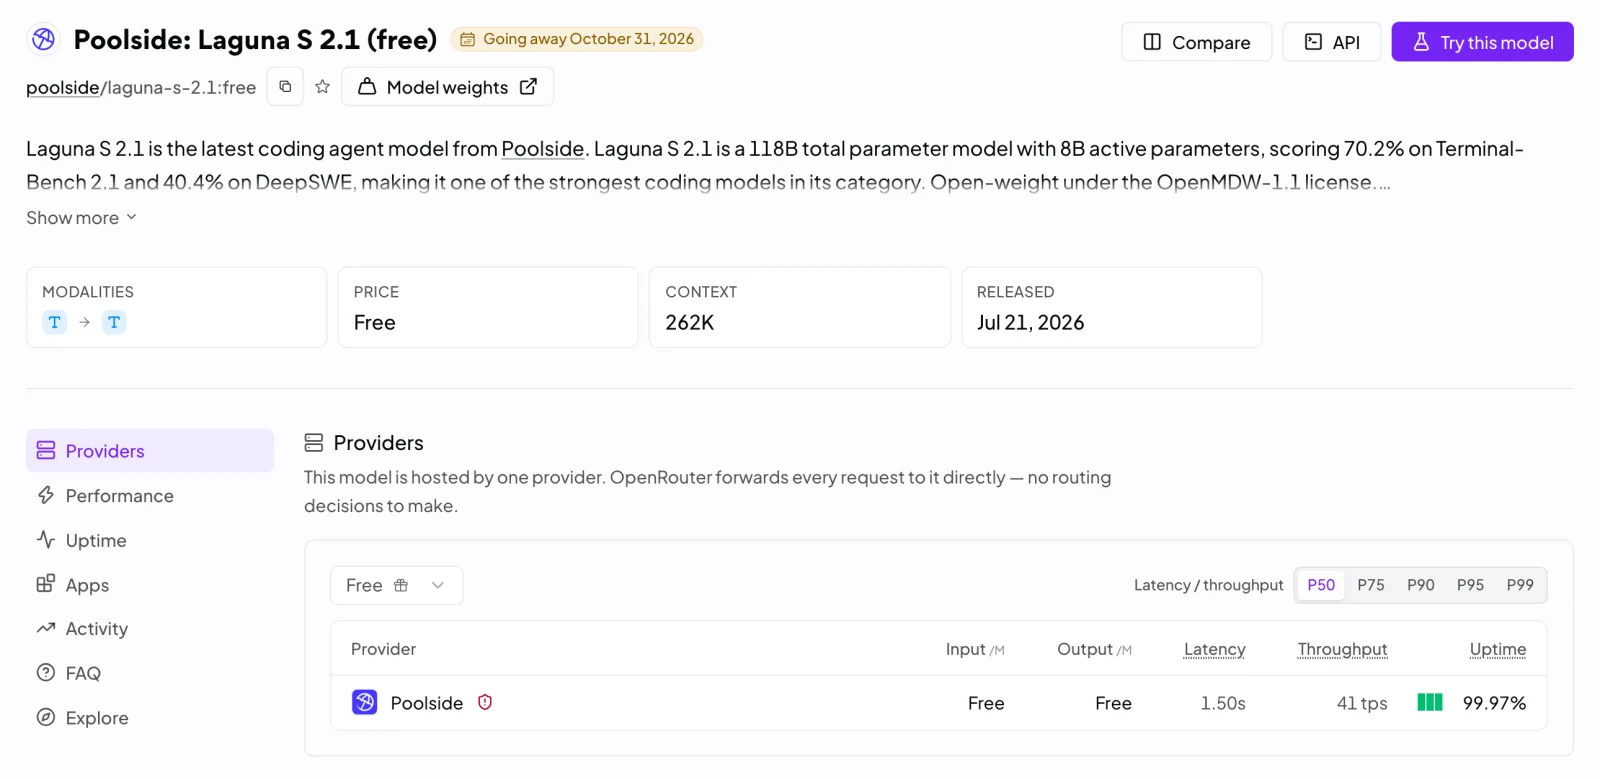
Screenshot: openrouter.ai/poolside/laguna-s-2.1:free, October 2026.
Laguna S 2.1 is Poolside’s coding-agent model: 118B total parameters, 8B active, open-weight under the OpenMDW-1.1 license, with a 262K context on the free endpoint. Poolside reports 70.2% on Terminal-Bench 2.1 and 40.4% on DeepSWE. Those are vendor numbers, but strong ones for a model with 8B active parameters, and of everything on the free list it’s the one most directly built for coding agents. That’s exactly the problem: the model page says “Going away October 31, 2026”, and the smaller poolside/laguna-xs-2.1:free (33B total, 3B active) expires the same day. Poolside also says it may use free-tier inputs and outputs to train its models. And it isn’t only the free tier that’s ending: the paid listing ($0.09/M input, $0.18/M output, 1M context) shows the same “Going away October 31, 2026” date, as does the paid Laguna XS 2.1.
We’re calling it out because free-tier listicles go stale within weeks. After October 31, 2026, check its current listing before you use it.
The Rest of the Current Free Roster
Beyond those five, the free chat models are Inkling Small; NVIDIA’s Nemotron 3.5 Lightning, Nemotron 3 Nano Omni (30B-A3B, with text, image, audio and video input) and the 4B Nemotron 3.5 Content Safety guardrail model; Cohere’s North Mini Code (30B, 3B active), its first agentic coding model; Recursive’s Flint (40B, 2.5B active), built for coding agents and added on October 21; China Telecom’s Xing4.0 29B-A4B; Dots Studio’s Dots3-Note Preview (280B, 16B active), free until December 31, 2026; and LiquidAI’s LFM2.5-2.6B for small, fast jobs. Outside chat, there are free embedding and reranking models from NVIDIA and LiquidAI, and free text-to-speech from Fish Audio and HeyGen (HeyGen’s until November 30).
For open-weight models you can run on your own hardware instead of depending on a rotating free tier, see our self-hosted LLM coding guide.
What the Free Endpoints Do With Your Prompts
Rate limits are the documented cost of the free tier. The less obvious one is data. Three of the five model pages above say the provider logs free-tier traffic or may train on it: NVIDIA and Thinking Machines log it to improve their models, and Poolside may train on it. That’s the deal behind most free inference: you get the tokens, and the lab gets real-world usage.
OpenRouter lets you opt out, at a price. Your account’s privacy settings have separate switches for paid and free models on whether to allow providers that may train on your data, and per OpenRouter’s provider logging docs, if you opt out, “OpenRouter will not route to providers that train.” Every free model in this guide runs on a single provider, so opting out doesn’t move you to a safer host; it takes those models off the table for your account. If a free model works for everyone else but fails for you, check that setting first.
Free Tier vs. Paying: What You Actually Give Up
The free tier isn’t a stripped-down demo. The biggest free models are frontier-scale open-weight releases, and on Inkling and Nemotron 3 Ultra the free endpoint offers a bigger context window than the paid listing. What you give up by staying free:
- Proprietary flagships. Free models on OpenRouter are open-weight releases (Inkling, Nemotron, Gemma, Laguna) or temporary promotions. You won’t find free access to Claude, GPT or Gemini’s flagship tiers.
- Throughput. 50 or 1,000 requests a day is fine for personal projects and prototyping. It isn’t enough for a production app with real traffic, and OpenRouter itself warns that free models can be rate limited or slower at peak times.
- Privacy. As covered above, many free endpoints log or may train on what you send.
Once you outgrow it, pay-as-you-go charges each provider’s list price with no markup on tokens, plus the 5.5% fee when you buy credits. If you already have keys with OpenAI, Anthropic or Google, BYOK (bring your own key) routes through them with no OpenRouter fee on the first $25,000 of list-price inference each month and 5% after that, per the pricing page. For gateways beyond OpenRouter, our LLM router comparison covers Portkey, LiteLLM and others, and our OpenRouter production pitfalls post covers what breaks when you move paid traffic onto it.
A Realistic Way to Use This
The pattern that holds up over time looks like this: build against the OpenAI-compatible endpoint so you’re never locked into one provider’s SDK, put two or three free models in a models fallback array instead of trusting any single one, check free_model_daily_requests before long runs, and keep confidential data on paid endpoints whose data policy you’ve read. Treat stealth models and time-limited listings like Laguna S 2.1 as bonus capacity, not something a workflow depends on.
Conclusion
“Free AI API with unlimited tokens” is a catchy search phrase, but the accurate description is more useful once you understand it: OpenRouter gives you free, per-token-uncapped access to a strong and changing set of open-weight models (right now Inkling, Nemotron 3 Ultra, Nemotron 3.5 Super VL and Gemma 4), gated by a daily request limit rather than a token limit. Fifty requests a day costs nothing and needs no card; $10 of credits, bought once, raises that to a thousand. The discipline it asks for hasn’t changed since July: build for rotation from day one, read each free endpoint’s data notice, and recheck model pages before you rely on them.